IB Maths AI HL 统计 标准差 回归 贝叶斯 卡方
IB 的数学课程在 2019 年 9 月换过一次框架,AI 这条线把统计与概率放在了课程的中轴上。旧版大纲里它更像附带模块,现在它既单独成题,也渗进别的主题的题干。AI HL 的统计题很少给纯计算,多数先摆一段真实情境,再问你能从中得出什么。下面这十几个知识点,是学生在 Paper 1、Paper 2 与 Paper 3 上反复卡住的地方。
Statistics sits at the centre of the Applications and Interpretation course rather than at its edge. A typical AI HL question hands you a context first, often a survey or a small data set, and only then asks what can reasonably be concluded. The arithmetic is rarely the hard part; deciding which model the data actually supports is where the marks live.
试卷结构与统计题的分值位置
IBO 在 2019 年 9 月启用的《Mathematics: applications and interpretation guide》把内容分成五个主题,统计与概率是第四个。AI HL 考三张卷子。Paper 1 与 Paper 2 各两小时、各 110 分,各占 30%。Paper 3 一小时、55 分,占 20%,两道题都落在真实情境上。内部评估的 exploration 再占 20%。AI 的两张长卷都允许使用图形计算器,AA 的 Paper 1 不允许,跨线选课的学生常把这一条记反。IBO 的公式手册已经给足标准差、相关系数、回归线、卡方与 t 检验的表达式,背公式并不是统计部分的门槛。
The HL course is assessed through three written papers plus an internally assessed exploration. Papers 1 and 2 each run for two hours and carry 110 marks, and the short Paper 3 is built around two extended real-life investigations. A graphic display calculator is expected in both long papers on this route, which is the opposite of the rule students meet if they move over from Analysis and Approaches. Because the formula booklet supplies the standard expressions, memorisation is not where marks are usually lost. What separates a 5 from a 7 is reading the calculator output correctly and then committing to an interpretation.
抽样方法与偏差的判断
抽样题的题干通常很短,信息全藏在描述收集方式的那句话里。IB 要你判断样本是否随机、哪一类人被过度代表、结论能推广到谁。便利抽样取的是手边最容易找到的人,结论只能停在这些人身上。自愿回应样本会系统性偏向意见强烈的一端,测出来的比例本身就偏了。问卷措辞带引导性时,比例再好看也没法用。公式手册里查不到这些,只能读题时把收集方式那一句圈出来。很多学生以为抽样只是背景介绍,其实后面每一小问都建在它上面。
Sampling items look brief, but the decisive information is hidden in the sentence describing how the data were gathered. Candidates are expected to judge whether the sample was random, whether one group is over-represented, and how far any conclusion can travel. A convenience sample drawn from a single class tells you about that class and very little else; voluntary responses over-weight people who feel strongly, which quietly inflates whichever proportion is being measured. None of this appears in the formula booklet, so the only route is to underline the collection method before touching the arithmetic. Students who skim that sentence tend to answer the later generalisation part in exactly the wrong direction.
标准差与四分位距的选择
标准差把每个数和均值的距离平方后累加,所以一个极端值就能把它抬起一大截。四分位距只看中间一半的数据,抗离群值。数据明显偏斜时,报中位数配四分位距比报均值配标准差诚实得多。计算器一般同时给出样本标准差与总体标准差,题目要哪一个得看上下文。从样本推断总体时用样本标准差,这是一条容易被忽略的默认约定。常见的错误是两种标准差混用,答案与评分方案只差一个很小的系数,整题却拿不到分。
Standard deviation squares every deviation from the mean, so a single extreme observation can move it a long way. The interquartile range describes only the middle half and is therefore far less sensitive to outliers. When a distribution is clearly skewed, quoting the median with the interquartile range gives a more honest summary than the mean with the standard deviation. Calculators return two values, and which one is wanted depends on whether the data are treated as a sample or as a whole population; mixing them is a routine slip that shifts the answer by a small factor and can cost the entire part.
箱线图与 1.5 倍四分位距的异常值线
画箱线图之前先排序,再按位置找出中位数与上下四分位数。数据个数是奇数还是偶数,会改变中位数的取法,也改变四分位数的落点。IB 的教学口径把超出下四分位数减 1.5 倍四分位距、或超出上四分位数加 1.5 倍四分位距的点当作异常值,须就画到最远的非异常点上。这套规则是约定,不是定理,答 justify 类小问时值得点明。异常值本身不是错误数据,删掉之前要给理由。题目常追问这个点代表测量误差还是真实的极端个案,回答必须回到情境。
Sort the values first, then locate the median and both quartiles by position, since an odd or even count changes how each is taken. The convention taught on this course treats anything beyond 1.5 interquartile ranges past either quartile as an outlier, and the whiskers then stop at the most extreme value that survives the test. The rule is a convention rather than a theorem, worth saying out loud when a question asks for justification; an outlier is not automatically a mistake, and removing it needs a reason grounded in the context. Most follow-up parts ask whether the point reflects a measurement error or a genuine extreme case in the population.
Pearson 相关系数的读法
Pearson 相关系数 r 只衡量线性关系的强弱与方向,取值从负一到正一。r 接近零说明线性关系弱,不说明两个量无关,它们可能呈很干净的曲线关系。r 为正只说明同向变化,推不出因果。样本很小的时候,一两个点就能把 r 拉到 0.8 以上。r 的平方描述回归线解释了多大比例的变异,引用时要带上数据范围。题目给出散点图与 r,通常是要你判断这条线在该情境里站不站得住。
The Pearson coefficient measures only the strength and direction of a straight-line relationship, on a scale from minus one to plus one. A value near zero rules out a strong linear pattern rather than a relationship of any kind, since a clean curve can produce almost no correlation. Positive correlation says the two quantities move together and says nothing about which one drives the other. With a small sample, one or two unusual points are enough to push r past 0.8, which is why the scatter diagram matters as much as the number. Its square reports the proportion of variation the fitted line accounts for, and it should be quoted alongside the range of the data.
最小二乘回归线与外推的风险
最小二乘回归线让竖直方向残差的平方和最小,它最小化的是 y 方向的偏差,不是点到线的垂直距离。把 x 与 y 对调,得到的不是同一条线。这条线一定经过两个变量的均值点。在数据范围之内插值,风险不大。把线延长到范围之外做外推,几乎每个情境都会失真。常见的错误是拿一条拟合两年销量的线去预测十年后的销量,还写得很自信。题目要求评价模型时,先看数据范围,再看残差图里有没有系统性的弯。
The least squares line is chosen to minimise the sum of squared vertical residuals, protecting against error in the response variable rather than measuring perpendicular distance to the points. Swap the two variables and a different line appears, so the choice of axis is a modelling decision rather than a formatting one. Every such line passes through the point of means. Interpolation inside the observed range carries a modest risk, while extending the line well beyond it usually fails because the context stops behaving in the same way; a confident ten-year forecast from a line fitted to two years of sales is the textbook version of that mistake. When asked to evaluate a model, check the data range first and then look for curvature in the residual plot.
条件概率与树状图
条件概率的符号读作在 B 已经发生的条件下 A 的概率,分母换成了 B 的概率。树状图是第一遍的抓手,每一条路径乘起来是联合概率,所有路径相加是一。反向问的时候,同一棵树要重画,把已知结果放在前面。两件事独立意味着条件不带来新信息,联合概率直接相乘。互斥说的是不能同时发生,和独立完全是两回事,这两个词混用是答题最常见的硬伤。题目里出现 given that 三个词,就要立刻把分母换掉。
Conditional probability divides by the probability of the condition, which is the single change that trips up most attempts at these questions. A tree diagram handles the forward direction well, with each path multiplied into a joint probability and all paths summing to one; a reversed question needs a redrawn tree with the known outcome placed first. Independence means the condition supplies no new information, so the probabilities simply multiply, whereas mutually exclusive events cannot occur together at all. Treating those two ideas as interchangeable is the most common conceptual error in the whole topic; the phrase given that is the signal to replace the denominator before anything else.
贝叶斯定理把条件反过来
贝叶斯定理处理的是已知结果、反推原因的问题,形式上是条件概率的一次重排。分子是原因条件下结果的概率乘上原因本身的概率,分母是这个结果在所有原因下的总概率。医学检测是标准载体:患病率很低时,即使检测很准,阳性结果里真患病的比例也可能低到让人意外。算完之后要解释这个比例的含义,只写数字拿不到最后一分。树状图在这里同样管用,把人群拆成有病与无病两支,各自乘上检测结果。很多学生以为阳性就等于患病,题目正是要打破这个直觉。
Bayes' theorem reverses a conditional probability: given an outcome, what caused it. The numerator multiplies the probability of the outcome under a cause by the prior probability of that cause, and the denominator totals the outcome across every cause. Medical screening is the standard vehicle, and with a low base rate even an accurate test can return a surprisingly small share of true cases among positives; explaining what that share means in context is usually a mark on its own. A tree split into affected and unaffected branches, each followed by the test result, keeps the bookkeeping honest; assuming a positive result means the condition is present is exactly the intuition the question is designed to unsettle.
离散随机变量的期望与方差
离散随机变量的期望是每个取值乘上对应概率再求和,它是长期平均值,不是最可能出现的值。方差有两条等价路径:按定义算每个偏差的平方加权,或者用平方的期望减去期望的平方。第二条在计算器上更快,手算时更不容易出错。概率表里所有概率相加必须是一,这一步能抓出抄错的条件。线性变换下期望直接跟着缩放平移,方差只随缩放系数的平方变化,加常数不影响方差。题目要求解释期望的含义时,措辞要落在重复试验的平均结果上。
The expected value of a discrete random variable weights each outcome by its probability, and it describes a long-run average rather than the most likely single result. Variance can be computed from the definition by averaging squared deviations, or more quickly as the mean of the squares minus the square of the mean. Probabilities in the table must total one, which is a cheap check on a mis-copied value. Under a linear transformation the expectation shifts and scales with the variable, while the variance scales with the square of the multiplier and ignores any constant added; when asked to interpret an expectation, describe the average over many repetitions rather than predicting one outcome.
二项分布的条件与计算
二项分布要同时满足四条:试验次数固定、每次只有成功与失败两种结果、每次成功的概率相同、各次试验相互独立。题干里出现从一批货里不放回地抽取,独立性就断了,这时该考虑超几何而不是二项。记号写作 B(n, p),期望是 n 乘 p,方差是 n 乘 p 再乘 1 减 p。至少、至多这类问法要用累积概率,或者用一减去对立事件,计算器上两者结果相同但写法更省时间。常见的错误是把至少三次直接算成恰好三次。
A binomial model needs a fixed number of trials, two possible outcomes per trial, a constant probability of success, and independence between trials; sampling without replacement from a finite batch breaks that independence, which is the point at which a hypergeometric model becomes the honest choice. Written as B(n, p), the mean is n times p and the variance is n times p times one minus p; questions phrased as at least or at most call for cumulative probabilities, and the complement is often the quicker route on a calculator. The routine slip is answering exactly three when the question asked for at least three.
正态分布与标准化
正态分布由均值与标准差两个参数定死,记号写作 N(mu, sigma squared)。标准化就是减去均值再除以标准差,把任意正态变量搬到标准正态上。正向问题是给区间求概率,反向问题是给概率求分位点,计算器上对应两个不同的功能。反向问题要看清给的是左侧面积还是中间面积,中间面积得先劈成两半。理论上的正态分布取值没有上下界,用正态近似有界量时要提到这一点作为限制。题目问模型是否合适,答的是对称性与离散程度,不是算出来的数字。
A normal distribution is fixed entirely by its mean and standard deviation, written as N(mu, sigma squared); standardising subtracts the mean and divides by the standard deviation, moving any normal variable onto the standard scale. Forward problems give an interval and ask for a probability, while inverse problems give a probability and ask for a cut-off point, and these are separate calculator routines; for an inverse problem, check whether the area given is a left tail or a central region, since a central region must be halved first. A theoretical normal variable has no upper or lower bound, which is worth stating as a limitation when the quantity being modelled cannot be negative. Judging whether the model fits calls for comments on symmetry and spread rather than another number.
卡方独立性检验与拟合优度
卡方统计量把每个格子的观测频数与期望频数作差、平方、再除以期望频数,最后全部相加。独立性检验的自由度是行数减一乘列数减一,拟合优度的自由度是类别数减一,这两条弄反,临界值就查错。期望频数全部来自行列合计,不是自己估的。检验的结论只能写成在该显著性水平下没有足够证据拒绝原假设,不能写成证明了两个变量无关。期望频数小于五的格子太多时,通常要合并类别。题目几乎总会要求把结论放回情境写一句。
The chi-squared statistic squares the gap between observed and expected frequencies in each cell, divides by the expected value, and sums over all cells; degrees of freedom are rows minus one times columns minus one for a test of independence, and categories minus one for goodness of fit, and swapping those two ruins the critical value. Expected frequencies come from the row and column totals rather than from a guess. A conclusion should say there is insufficient evidence to reject the null hypothesis at that significance level, not that the two variables have been proved unrelated; cells with expected counts below five usually need merging before the test is valid. Almost every such question expects one sentence putting the result back into the context.
HL 专属的双样本 t 检验与等级相关
双样本 t 检验比较两组均值,前提是两组数据近似正态、彼此独立。自由度按两组样本量之和减二计算,检验统计量用均值差除以合并标准误。Spearman 等级相关系数先把数据换成名次再算相关,对异常值不敏感,适合有序评分或明显偏斜的数据。名次并列时要取平均名次,这一步漏掉,系数会偏。两个检验的原假设写法固定,拒绝与不拒绝的措辞同样固定。阅卷时看到最多的是 p 值算对、结论句写反。
The two-sample t test compares two means on the assumption that each group is roughly normal and the groups are independent. Degrees of freedom come from the two sample sizes added together minus two, and the statistic divides the difference in means by a pooled standard error. Spearman's rank coefficient converts the data to ranks before correlating, which makes it insensitive to outliers and suited to ordered ratings or clearly skewed measurements. Tied ranks must be averaged, and skipping that step biases the coefficient; the null hypothesis and the wording of a rejection are both fixed conventions, and examiners see more marks lost to a reversed conclusion than to the arithmetic.
计算器操作与阅卷丢分点
统计题的很多分不在数学上,而在读对计算器的输出。双变量数据要确认进的是列表不是单变量表,回归前先看散点图。卡方与 t 检验在计算器里各有入口,输出会给出 p 值,但题目要的往往是检验统计量与自由度。答案的精度跟着题目要求走,中间步骤不要提前取整。写结论时把情境里的两个变量名字写进去,别只写拒绝原假设。每一步都留一行说明你用的是什么检验、为什么,这句说明本身就是分。
A good share of the marks in this topic comes from reading calculator output correctly rather than from mathematics; for bivariate data, check that the values went into list columns and not a single-variable screen, and plot the scatter diagram before fitting anything. Chi-squared and t routines each live under their own menu, and although the p value is displayed, the question usually wants the test statistic and the degrees of freedom as well. Precision should follow the demand of the question, with no premature rounding in intermediate steps. Name the two variables from the context in the conclusion instead of writing only that the null hypothesis is rejected; one line stating which test was used and why is itself worth marks.
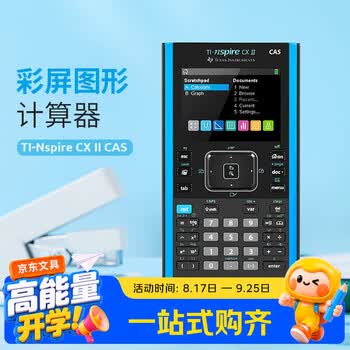
TI-Nspire CX II CAS 图形计算器 AP/IB/A-Level¥1320📱 去京东购买京东精选
需要一对一辅导?Need One-on-One Tutoring?
IB / A-Level / GCSE / KS2-KS3 全科辅导,统计与概率专项可单独安排
16621398022 同微信
Visit aleveler.com
或截图后用「扫一扫 → 相册」选择本图