Edexcel A-Level 统计高分备考全攻略
一、考试结构与评分标准解读 | Exam Structure and Marking Criteria
Edexcel A-Level数学中的统计部分分布在各个单元中。对于A-Level Mathematics,统计内容与力学合并为一个试卷(Paper 3: Statistics and Mechanics),占总分的约50%。而对于Further Mathematics,Statistics作为独立单元出现(FS1、FS2等)。理解各单元的分值权重和题型分布是备考的第一步:Paper 3通常包含约5-6道统计大题,涵盖数据分析、概率、分布和假设检验等核心模块。每道题分值从4分到12分不等,大题的最后一问往往是综合分析或解释题,要求用统计语言清晰表达结论。
The Statistics component in Edexcel A-Level Mathematics appears in Paper 3 alongside Mechanics, accounting for roughly 50% of the paper. For Further Mathematics, Statistics stands alone as separate units (FS1, FS2). Paper 3 typically features 5-6 multi-part statistics questions covering data analysis, probability, distributions, and hypothesis testing. Each question ranges from 4 to 12 marks, with the final sub-question often requiring clear conclusions expressed in proper statistical language. Understanding this structure helps you allocate revision time proportionally to each topic's weight.
二、统计抽样方法的核心区分 | Statistical Sampling Methods
抽样是统计学的基础。Edexcel考试中高频出现的抽样方法包括:简单随机抽样(Simple Random Sampling)、分层抽样(Stratified Sampling)、系统抽样(Systematic Sampling)、配额抽样(Quota Sampling)和机会抽样(Opportunity Sampling)。考试中常要求你区分这些方法的优缺点。例如,分层抽样能确保各子群体的代表性,但实现成本较高;机会抽样虽然方便,但容易引入偏差。典型考题会给一个场景,要求你推荐最合适的抽样方法并给出理由,同时指出该方法的一个局限性。
Sampling forms the foundation of statistics. High-frequency methods in Edexcel exams include simple random sampling, stratified sampling, systematic sampling, quota sampling, and opportunity sampling. Exam questions often ask you to distinguish advantages and disadvantages: stratified sampling ensures subgroup representation but costs more to implement, while opportunity sampling is convenient yet prone to bias. A typical question presents a scenario and asks you to recommend the most suitable method with reasoning, then identify one limitation. Memorise the key features of each method and practice matching them to real-world contexts.
三、数据呈现技巧:直方图与箱线图的精准作图 | Data Presentation: Histograms and Box Plots
数据呈现题是统计试卷的基础得分项,但细节失误频频导致扣分。直方图(Histogram)的关键在于频率密度(Frequency Density = Frequency / Class Width)的计算,很多学生直接用频率作为纵轴高度而丢分。箱线图(Box Plot)必须标注最小值、下四分位数(Q1)、中位数(Q2)、上四分位数(Q3)和最大值,离群值(Outliers)的判断标准是 1.5 × IQR 规则。累积频率图(Cumulative Frequency Diagram)要连接的是各区间上限对应的累积频率点,而非区间中点。考试中还常把直方图和箱线图放在同一道题里,要求你在两种可视化之间相互转换信息。
Data presentation questions are reliable mark-earners, but detail errors cost points frequently. The key to histograms is frequency density (Frequency / Class Width): many students incorrectly use frequency as the bar height. Box plots must clearly label minimum, Q1, median, Q2, Q3, maximum, and outliers using the 1.5 × IQR rule. Cumulative frequency diagrams connect points at each class's upper boundary, not the midpoint. Exams often combine histograms and box plots in one question, requiring you to translate information between the two representations. Practice drawing these graphs neatly and labelling axes correctly under timed conditions.
四、中心趋势与离散程度的完整度量 | Central Tendency and Dispersion Measures
均值(Mean)、中位数(Median)和众数(Mode)是中心趋势的三驾马车,而方差(Variance)和标准差(Standard Deviation)衡量离散程度。Edexcel考试中的计算题通常要求你同时计算均值和标准差,并解释它们的实际含义。需要注意:编码数据(Coded Data)的均值还原公式容易出错,公式为 y = (x - a) / b 时,x 的均值需要用 a + b × ȳ 还原。标准差则直接乘以 |b|。此外,比较两组数据时,不仅要指出哪组均值更高,还要分析哪组更稳定(标准差更小)。考官期望看到完整的比较陈述,而非孤立的数字。
Mean, median, and mode measure central tendency, while variance and standard deviation measure spread. Edexcel questions typically ask you to calculate both mean and standard deviation and interpret their real-world meaning. Watch out for coded data: if y = (x - a) / b, then the mean of x is a + b × ȳ, and the standard deviation of x is |b| × σy. When comparing two datasets, state which has the higher mean AND which is more consistent (smaller standard deviation). Examiners expect complete comparative statements, not isolated numbers. Practice explaining what the statistics tell you about the context, not just reciting calculated values.
五、概率基础与条件概率的Venn图解法 | Probability and Venn Diagrams
概率题从基础的互斥事件(Mutually Exclusive Events)和独立事件(Independent Events),到复杂的条件概率(Conditional Probability),层层递进。Venn图是可视化概率关系的核心工具:两圆相交区域代表交集P(A ∩ B),条件概率P(A|B)是已知B发生时A发生的概率。树状图(Tree Diagram)在涉及多次试验(如两次抽取、两个阶段筛选)时尤其有用。考试技巧:标注概率时必须检查每一层分支的概率之和是否为1;处理"不放回"(Without Replacement)情景时,第二层的概率会因第一层的结果而改变。
Probability questions progress from basic mutually exclusive and independent events to complex conditional probability. Venn diagrams are essential for visualising probability relationships: overlapping regions represent intersections P(A ∩ B), while conditional probability P(A|B) is the chance of A given B has occurred. Tree diagrams excel in multi-stage scenarios like two draws or two-stage screening. Exam tip: always verify that branch probabilities at each stage sum to 1. For without-replacement scenarios, second-stage probabilities change based on first-stage outcomes. Practice distinguishing between P(A ∩ B) and P(A|B), as this is a common source of confusion in exam conditions.
六、离散随机变量与概率分布表 | Discrete Random Variables and Distribution Tables
离散随机变量(Discrete Random Variable)的概率分布可以用表格表示,列出每个可能取值及其对应概率。核心考点包括:构建概率分布表(所有概率之和必须等于1)、计算期望值E(X) = Σx·P(X=x)、计算方差Var(X) = E(X²) - [E(X)]²。Edexcel经常将离散随机变量与线性变换结合考查:E(aX+b) = aE(X) + b,Var(aX+b) = a²Var(X)。此外,两道独立随机变量组合的期望值与方差计算也是常见题型:E(X+Y) = E(X) + E(Y),Var(X+Y) = Var(X) + Var(Y)(仅当X和Y独立时)。
Discrete random variable distributions are expressed in tables listing each possible value and its probability. Core requirements: constructing distribution tables where probabilities must sum to 1, calculating expected value E(X) = Σx·P(X=x), and variance Var(X) = E(X²) - [E(X)]². Edexcel frequently tests linear transformations: E(aX+b) = aE(X) + b and Var(aX+b) = a²Var(X). Combinations of independent random variables also appear regularly: E(X+Y) = E(X) + E(Y) and Var(X+Y) = Var(X) + Var(Y) when X and Y are independent. Memorise these formulas and practice applying them to word problems where you must first identify the random variable from context.
七、二项分布与泊松分布的识别与计算 | Binomial and Poisson Distributions
二项分布(Binomial Distribution)B(n, p)适用于固定次数n的独立试验,每次试验只有成功或失败两种结果。识别关键词:"exactly"、"at least"、"more than"等。泊松分布(Poisson Distribution)Po(λ)适用于描述单位时间或空间内随机事件发生的次数,满足事件独立且平均发生率恒定。考试中常将两者放在同一道题中进行区分。关键计算技巧:二项分布的累积概率用计算器中的Binomial CD功能直接求解;泊松分布的概率公式P(X=r) = e^(-λ)·λ^r / r! 必须熟练掌握。当n很大且p很小时,泊松分布可作为二项分布的近似(λ = np)。
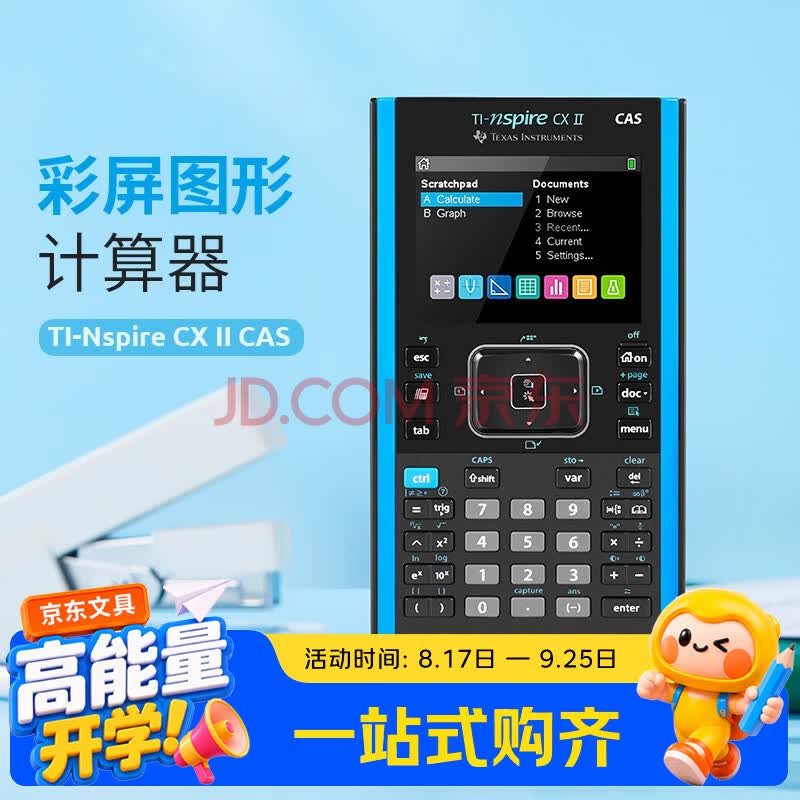
The Binomial distribution B(n, p) models a fixed number n of independent trials, each with two possible outcomes. Key words include "exactly", "at least", and "more than". The Poisson distribution Po(λ) describes the number of random events in a fixed interval, assuming events occur independently at a constant average rate. Exams frequently test both distributions side by side. Essential techniques: use your calculator's Binomial CD function for cumulative binomial probabilities, and master the Poisson formula P(X=r) = e^(-λ)·λ^r / r!. When n is large and p is small, Poisson approximates Binomial with λ = np. Practice choosing the correct distribution based on the problem context before diving into calculations.
八、正态分布与标准化技巧 | Normal Distribution and Standardisation
正态分布(Normal Distribution)是A-Level统计中最关键的连续分布。标准化的核心公式 z = (x - μ) / σ 必须烂熟于心。Edexcel考试中正态分布题通常要求你:已知x求概率P(X < x)或P(X > x),或已知概率反求x值(使用逆正态分布功能)。特别注意:P(X > x) = 1 - P(X < x);对称性意味着P(X < μ - a) = P(X > μ + a)。样本均值的分布(Distribution of Sample Mean)是关键考点:若X ~ N(μ, σ²),则X̄ ~ N(μ, σ²/n)。"求样本均值超过某值的概率"需要用到标准误σ/√n而非σ。
The Normal distribution is the most critical continuous distribution in A-Level Statistics. Master the standardisation formula z = (x - μ) / σ. Edexcel questions typically ask you to find P(X < x) or P(X > x) given x, or find x given a probability using the inverse normal function. Remember: P(X > x) = 1 - P(X < x), and symmetry gives P(X < μ - a) = P(X > μ + a). The distribution of the sample mean is a key topic: if X ~ N(μ, σ²), then X̄ ~ N(μ, σ²/n). Questions asking for the probability that a sample mean exceeds a value require the standard error σ/√n, not σ. This distinction is one of the most commonly tested fine points in the exam.
九、假设检验的完整解题框架 | Hypothesis Testing Framework
假设检验(Hypothesis Testing)是Edexcel统计中最具结构化特征的题型,严格按照五步法作答可得满分:第一步,明确写出零假设H₀和备择假设H₁,注意区分单侧检验(One-tailed)和双侧检验(Two-tailed);第二步,确定检验统计量(Test Statistic)及其分布;第三步,计算p值或在给定显著性水平(Significance Level)下找到临界值(Critical Value);第四步,比较p值与显著性水平α,或将检验统计量与临界值比较;第五步,用统计语言写出结论:"有/无充分证据拒绝H₀"并联系原始问题的上下文。常见失分点:结论只写"reject H₀"而忘了关联实际问题。
Hypothesis testing is the most structured question type in Edexcel Statistics. Follow the five-step framework to secure full marks. Step 1: state H₀ and H₁ clearly, distinguishing one-tailed from two-tailed tests. Step 2: identify the test statistic and its distribution. Step 3: calculate the p-value or find the critical value at the given significance level. Step 4: compare the p-value with α, or compare the test statistic with the critical value. Step 5: write a conclusion in statistical language stating whether there is sufficient evidence to reject H₀, and link back to the original problem context. A common pitfall is writing only "reject H₀" without connecting to the real-world question. Every conclusion must reference the original scenario.
十、相关性与回归分析的核心应用 | Correlation and Regression
积差相关系数(Product Moment Correlation Coefficient, PMCC)r衡量两个变量之间线性关系的强度和方向,取值范围[-1, 1]。Edexcel考试中通常使用计算器直接求得r值。回归直线(Regression Line)y = a + bx的系数b = Sxy / Sxx,截距a = ȳ - b·x̄。关键考点:回归方程只能用于在原始数据范围内进行插值预测(Interpolation),不能用于外推(Extrapolation),因为数据范围之外的关系可能不再成立。此外,要能解释回归系数b的实际含义:"x每增加1个单位,y平均变化b个单位"。对残差(Residuals)的分析也是潜在考点,残差 = 观测值 - 预测值。
The Product Moment Correlation Coefficient r measures the strength and direction of a linear relationship, ranging from -1 to 1. Use your calculator to find r directly in Edexcel exams. For the regression line y = a + bx, the slope b = Sxy / Sxx and intercept a = ȳ - b·x̄. Key exam point: regression equations should only be used for interpolation within the original data range, never extrapolation, as the relationship may not hold beyond observed values. You must be able to interpret the coefficient b: "for each unit increase in x, y changes by b units on average." Residual analysis (observed minus predicted values) may also appear. Practice drawing the regression line on scatter diagrams and explaining what the correlation coefficient tells you in context.
十一、常见失分陷阱与针对性避坑策略 | Common Exam Pitfalls and Solutions
根据历年Edexcel考官报告,统计试卷中最常见的失分原因包括:(1)假设检验中未明确写出H₀和H₁:即使你知道答案,缺少假设陈述会直接丢失方法论分数;(2)正态分布题中混淆σ和σ/√n:题目提到"sample mean"或"sample of n"时必须使用标准误;(3)概率分布表中概率之和不为1:建立分布表后养成检查总和的习惯;(4)结论缺少上下文:每道假设检验和相关性分析题的最后一步必须关联题干中的实际问题;(5)直方图中用频率代替频率密度:遇到不等宽区间(Unequal Class Widths)时尤其容易出错;(6)计算器使用不当:确保考前熟悉Binomial CD、Normal CD和Inverse Normal三个功能的操作。
Based on past Edexcel examiner reports, the most common pitfalls include: (1) failing to state H₀ and H₁ explicitly in hypothesis testing, which costs methodology marks even if your answer is correct; (2) confusing σ with σ/√n in Normal distribution problems; (3) probability distribution tables where probabilities do not sum to 1; (4) conclusions lacking context, which is required for every hypothesis test and correlation question; (5) using frequency instead of frequency density in histograms, especially with unequal class widths; (6) calculator errors from unfamiliarity with Binomial CD, Normal CD, and Inverse Normal functions. Review these six traps before the exam and check your work against each one systematically. A quick mental checklist can save 10-15 marks across the paper.
十二、考前冲刺复习计划与时间管理 | Revision Planning and Time Management
高效的统计备考需要分阶段推进。第一阶段(考前6-8周):系统梳理每个知识模块,对照Edexcel官方教材逐章做题,建立完整的公式手册。第二阶段(考前3-5周):集中刷近5年的真题(Past Papers),严格按照考试时间限时完成,每套卷子做完后对照Mark Scheme逐题分析得分点和扣分原因。第三阶段(考前1-2周):针对错题本中的高频错误类型进行专题突破,同时保持每周至少2-3套完整试卷的练习节奏以维持手感。考试当天的时间分配建议:先快速浏览全卷(2分钟),然后按顺序作答,每道统计大题控制在10-12分钟内完成,留出最后5分钟检查关键步骤和结论表述。
Effective Statistics revision should progress through phases. Phase 1 (6-8 weeks before the exam): systematically review each topic, work through textbook exercises, and build a complete formula reference sheet. Phase 2 (3-5 weeks before): focus on past papers from the last five years under timed conditions, then analyse every question against the mark scheme to understand exactly where marks are awarded and lost. Phase 3 (1-2 weeks before): target your most common error types from your mistake log while maintaining 2-3 full practice papers per week. On exam day, allocate 2 minutes to skim the paper, then tackle questions in order spending 10-12 minutes per statistics question, with 5 minutes at the end to check critical steps and conclusion statements. Consistent practice under timed conditions is the single most effective preparation strategy.
需要专业A-Level辅导?
16621398022
同微信 | 免费咨询课程规划
访问 aleveler.com 了解更多
更多咨询请联系16621398022(同微信)

或截图后用「扫一扫 → 相册」选择本图